Autonomous System Architecture
A personal AI second brain that captures, classifies, and acts.
Cortex is a self-hosted platform that turns a single Telegram thread into the front door for everything: text, voice, photos, documents, and links get classified by a local LLM and routed to Notion, Calendar, or one of three autonomous agents.
Role & Scope
AI Systems Architect
End-to-end design, orchestration & full-stack code
Scale
18 Intent Pipelines
Text, voice, vision, documents & agent loops
Core Bet
Tiered Model Routing
Zero-cost local triage + cloud frontier synthesis
Impact
<300ms Triage
Zero per-message cost on 90% of requests
Collapses a dozen capture apps into one message thread.
Instead of juggling a notes app, a task manager, a reminders tool, and a bookmark list, you send one Telegram message and Cortex figures out where it belongs. The friction of deciding which app to open disappears before it becomes an excuse to drop the thought.
Proves an agentic product can be private by default.
Cortex runs on your own hardware with AES-256-GCM encryption for secrets at rest and a one-command Docker deploy. Local inference handles classification for free, so the trade-off between intelligence and data ownership goes away.
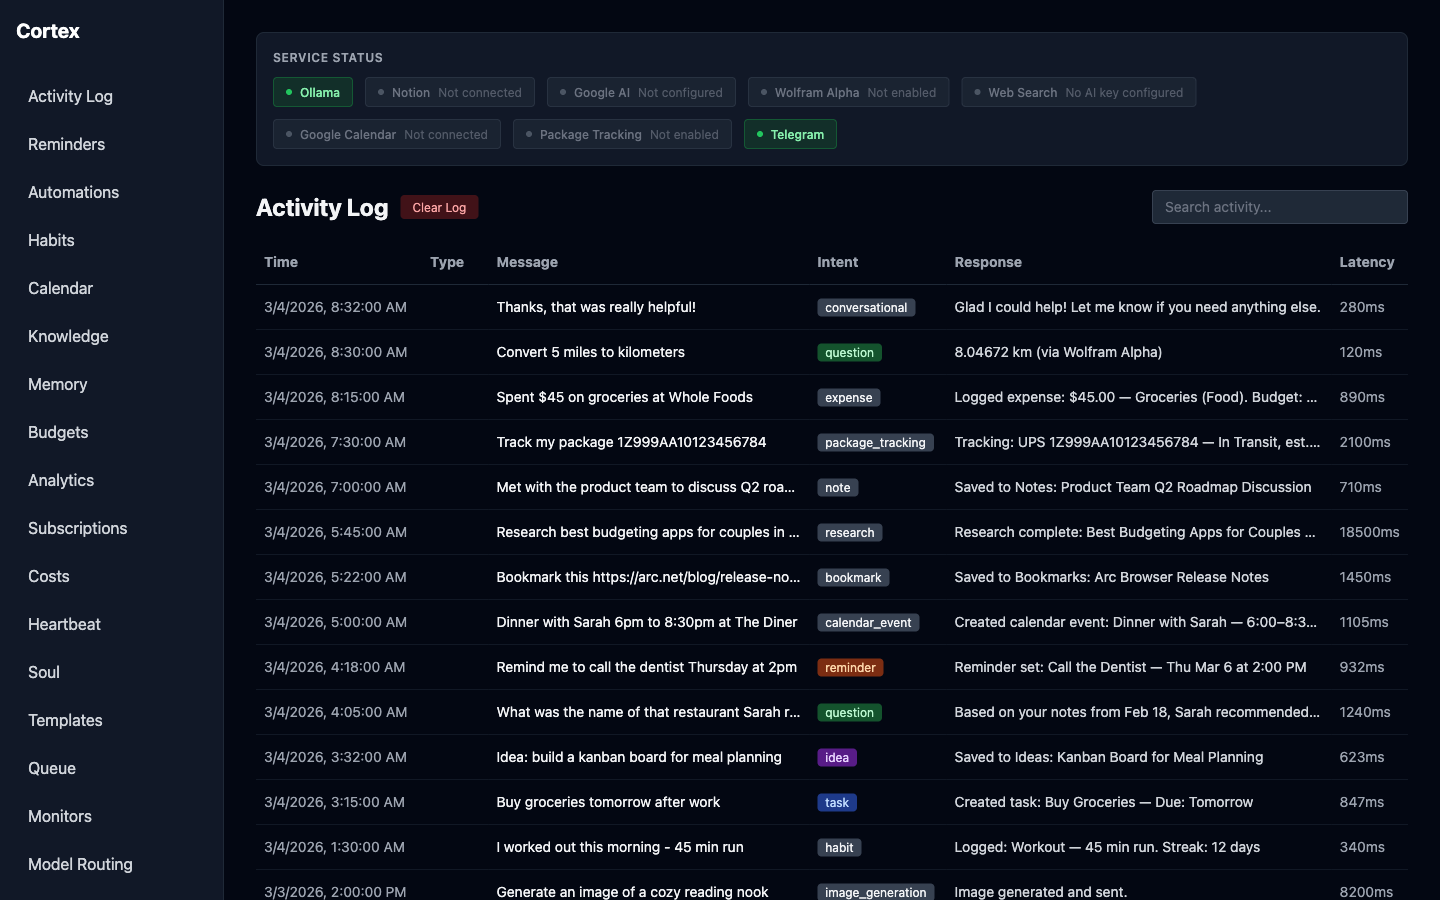
Activity log with service status badges and color-coded intent classification across 18 message types.
The Tooling Fragmentation
Ideas everywhere, home for none of them.
Personal knowledge was scattered across a dozen apps: tasks in one place, voice memos in another, bookmarks piling up in a browser tab graveyard. Every capture required picking the right tool first, which meant most thoughts never got captured at all.
Meanwhile, the AI tooling landscape was moving fast, but most of it was cloud-locked, subscription-based, and indifferent to where your data lived. A second brain that ran on someone else's servers and charged per API call wasn't a second brain — it was a rental.
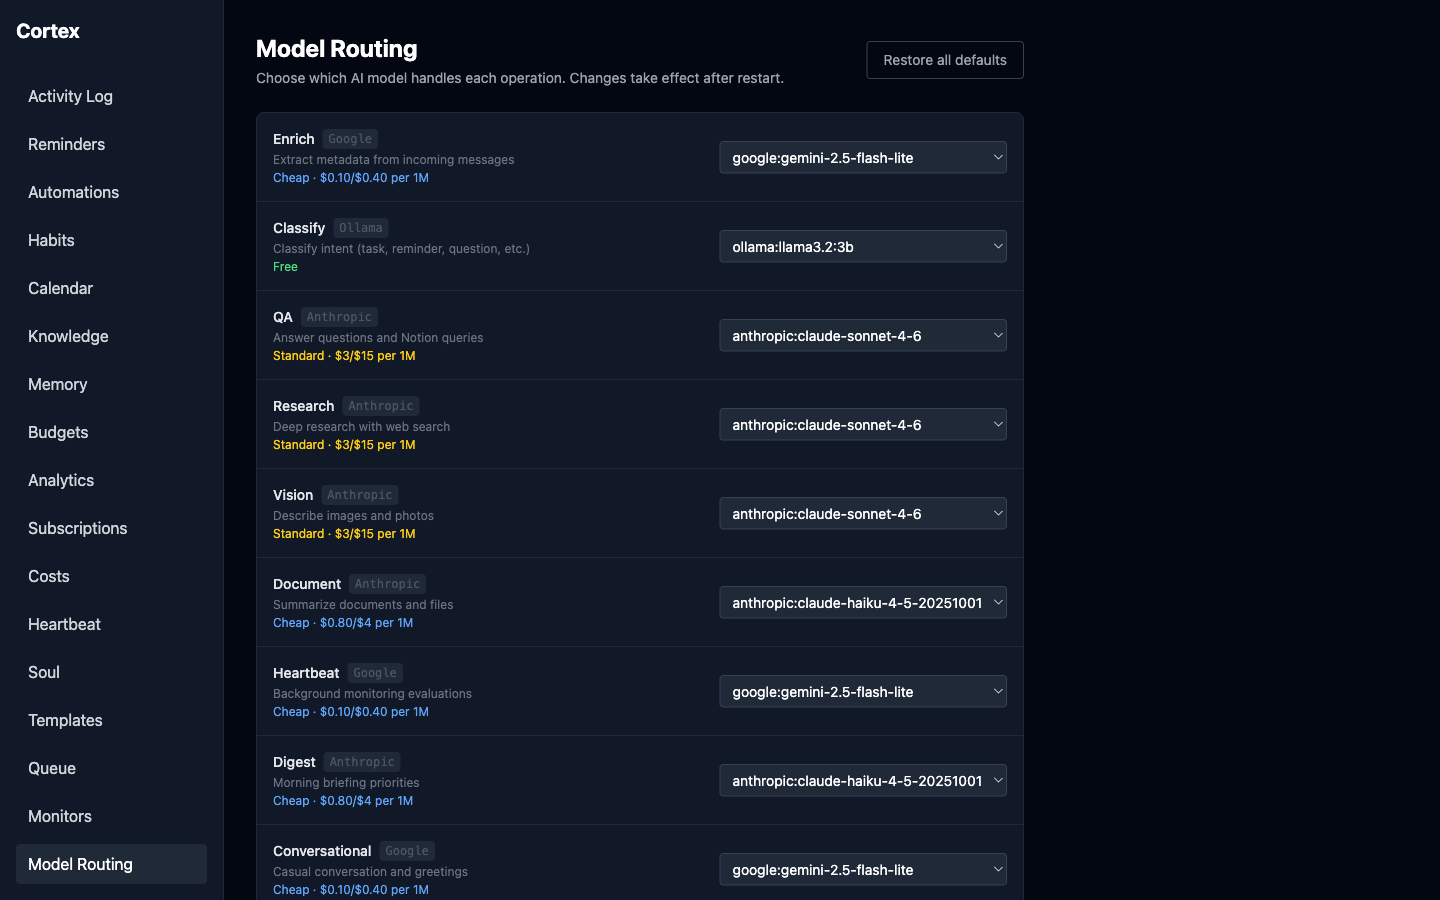
Per-operation model routing across Claude, Gemini, and local Ollama with visible cost tiers.
The Architectural Mandate
One thread in, the right destination out — without the cloud tax.
Build a self-hosted platform where any Telegram message — text, voice, photo, document, or URL — gets classified locally, enriched by a cloud LLM only when it matters, and routed automatically to Notion, Calendar, or an agent. The design target: unlimited capture with near-zero marginal cost, and personality the user can configure.
Strategic Trade-Offs (Model Orchestration Dilemma)
The forks in the road: orchestrating agentic autonomy vs. deterministic reliability.
When designing an autonomous second brain, the central architectural challenge is balancing latency, marginal API costs, and privacy against model intelligence. We evaluated and rejected two conventional AI pipeline patterns.
Pure Cloud Frontier Pipeline (All-in-One Calls)
The Premise: Send every single message, voice note, and document straight to a hosted frontier model (Claude 3.5 Sonnet / GPT-4) with an enormous multi-tool prompt.
Why It Failed: Unacceptable operating cost and latency. At hundreds of quick notes per day, API bills compound quickly, round-trip latency hovered around 2–4 seconds for trivial reminders, and personal thoughts were continually transmitted to third-party cloud logs.
Heuristic Slash-Commands & Regex Routing
The Premise: Require explicit prefix commands (e.g. /task, /cal, /note) and regex parsing to guarantee deterministic, zero-cost routing.
Why It Failed: It destroyed spontaneous mobile capture. In high-velocity voice notes or quick mobile shares while walking, forcing users to remember syntax creates immediate cognitive friction, causing capture abandonment.
Tiered Semantic Model Router with Local Pre-Flight
We engineered a tiered, multi-provider pipeline: a local LLM (Ollama / Llama 3.2) runs directly on self-hosted hardware to classify incoming intent across 18 taxonomy categories in <300ms with zero marginal cost and total privacy. Only if the classification requires deep synthesis, schema transformation, or web research does Cortex route to cloud frontier models (Claude 3.5 Sonnet or Gemini Flash). Users get effortless natural language capture, 90% zero-cost execution, and sub-second feedback loops.
Autonomous Pipeline Engineering
Four architectural milestones from script to self-hosted platform.
Local-First Ingestion: Zero-cost intent classification via Ollama
Started with a detailed PRD in Claude Code defining the pipeline: Telegram input to a local LLM (Ollama running Llama 3.2) for intent detection, then Claude enrichment for titles, dates, and tags, then a Notion API write. Running classification locally was a deliberate design decision — it meant unlimited messages without API spend, and set the cost ceiling for everything that came after.
Unified Intent Taxonomy: Scaling 18 capture modalities without architecture drift
Each new capture type — reminders, calendar events, bookmarks, package tracking, expenses, habits — followed the same shape: detect intent locally, enrich with a cloud LLM, route to the right destination. Holding the pattern steady made the product scale from a Telegram bridge into a real platform without the architecture collapsing under new features.
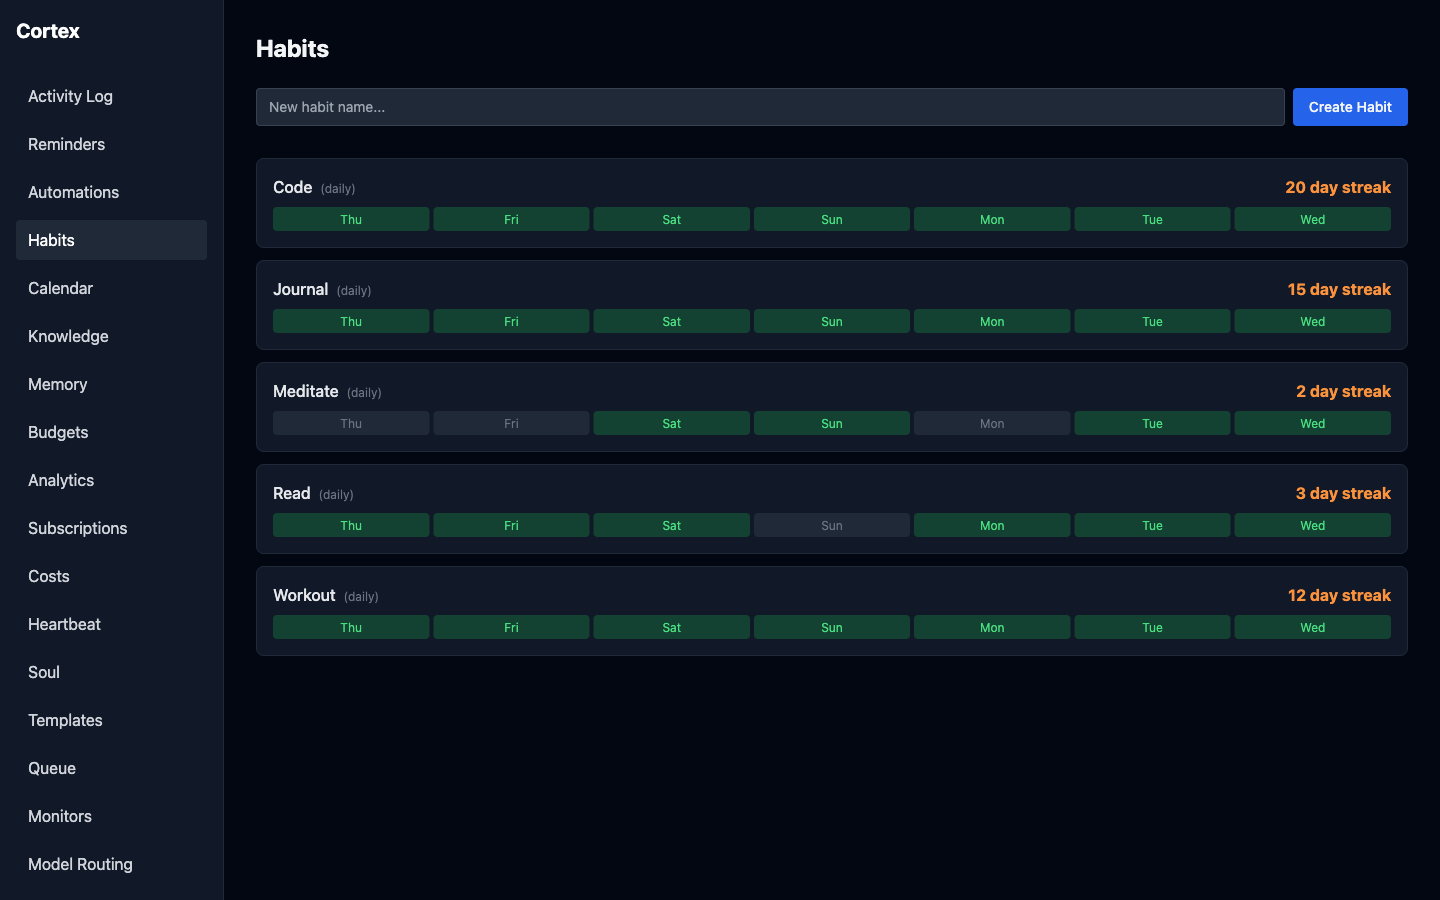
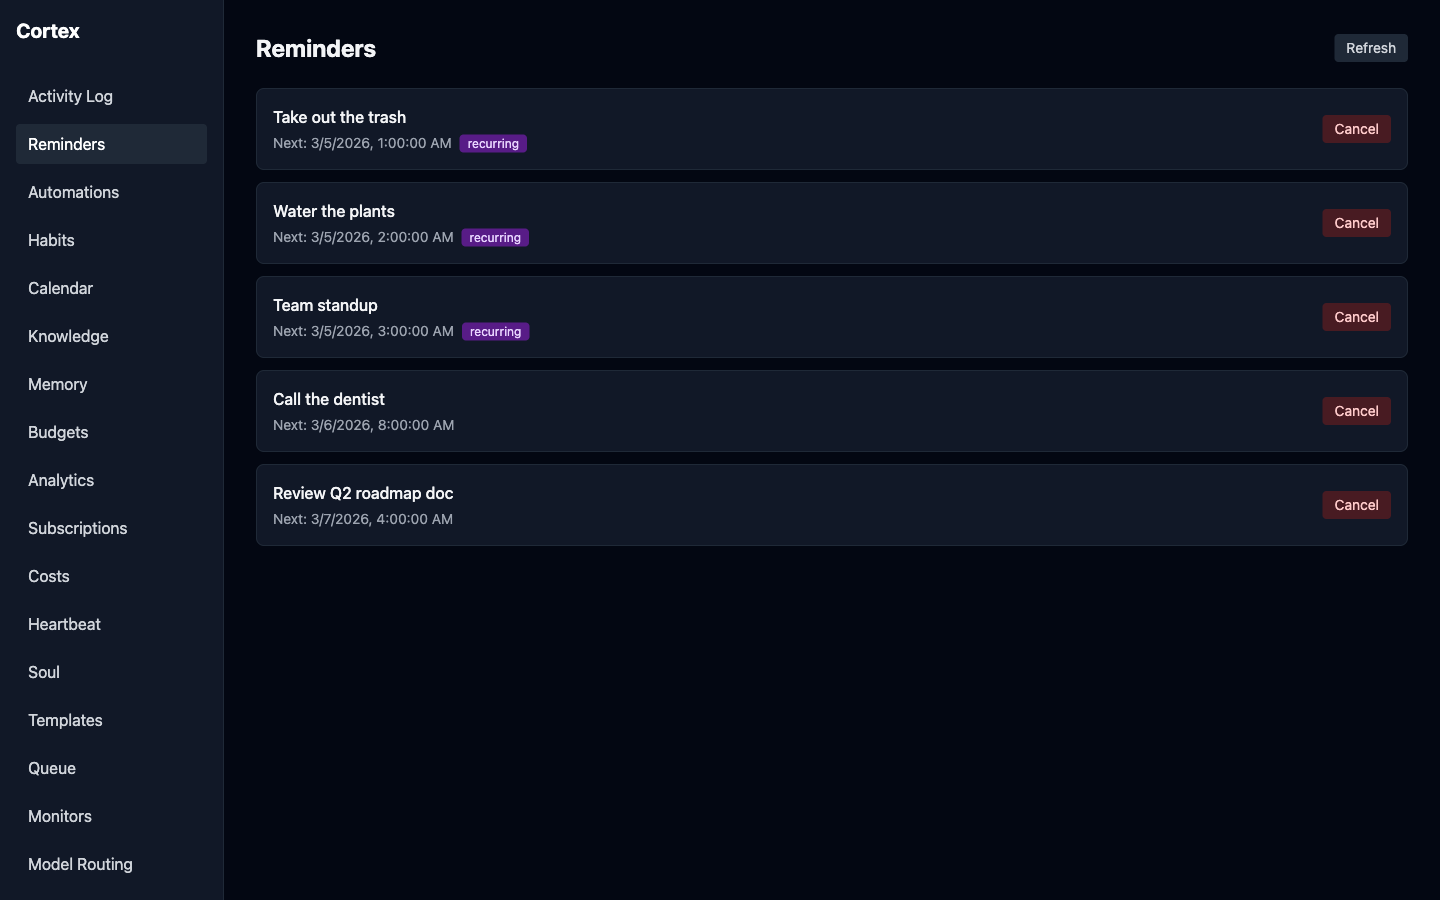
Tiered Cloud Enrichment: Selective Claude & Gemini model routing with visible cost
Claude Sonnet on every operation was wasteful when Gemini Flash or local Ollama could handle classification and casual conversation. Built a dashboard that assigns Claude, Gemini, or Ollama to each of the 10 operations independently, with per-million-token cost labels so the trade-offs are visible at the moment of choice instead of buried in a monthly bill.
Containerized Agent Orchestration: Multi-agent execution & encrypted self-hosting
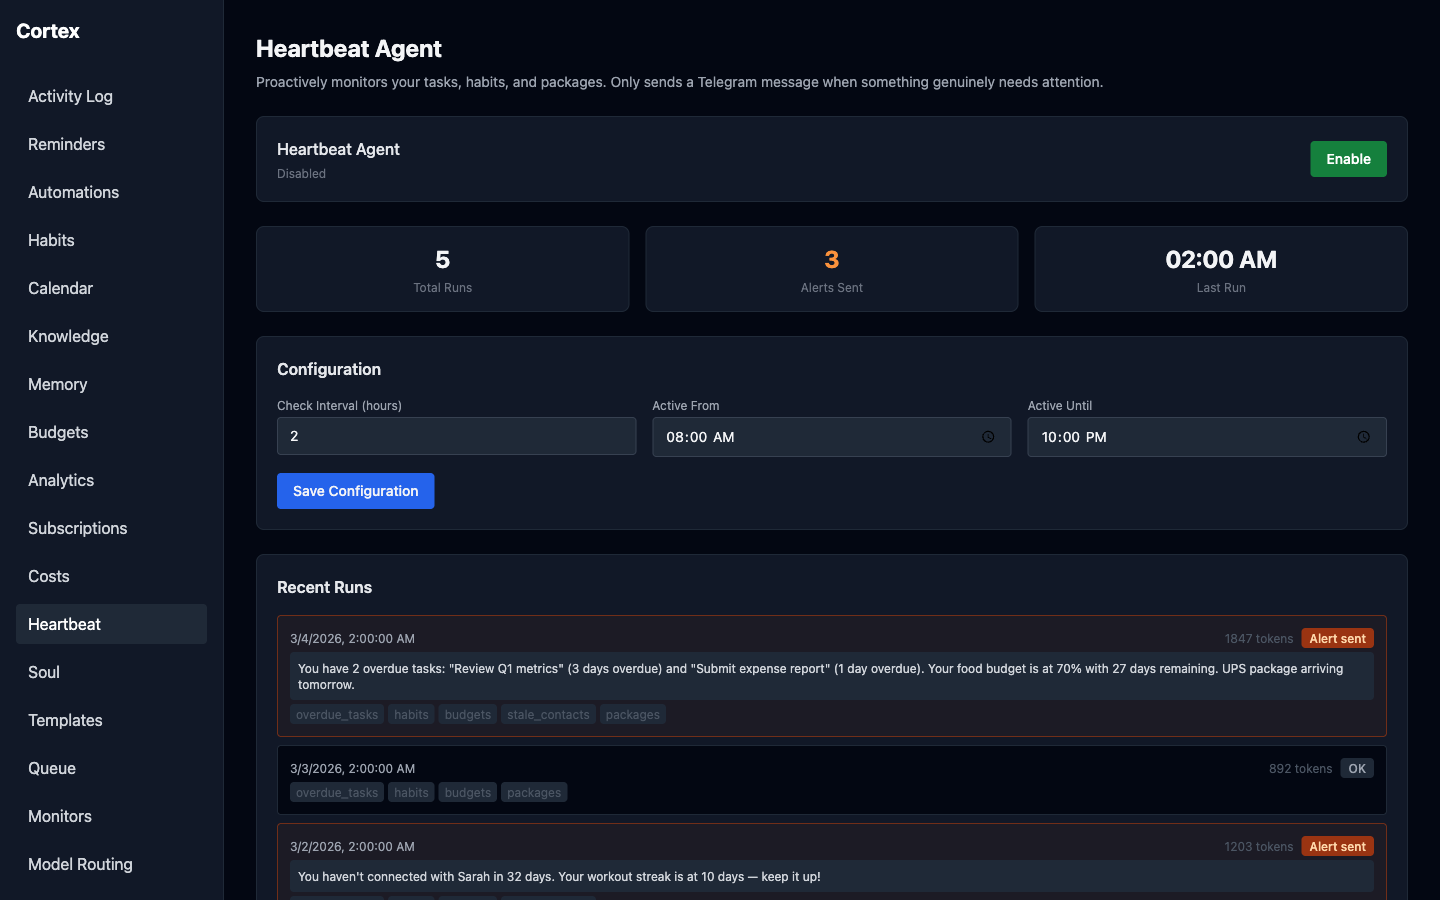
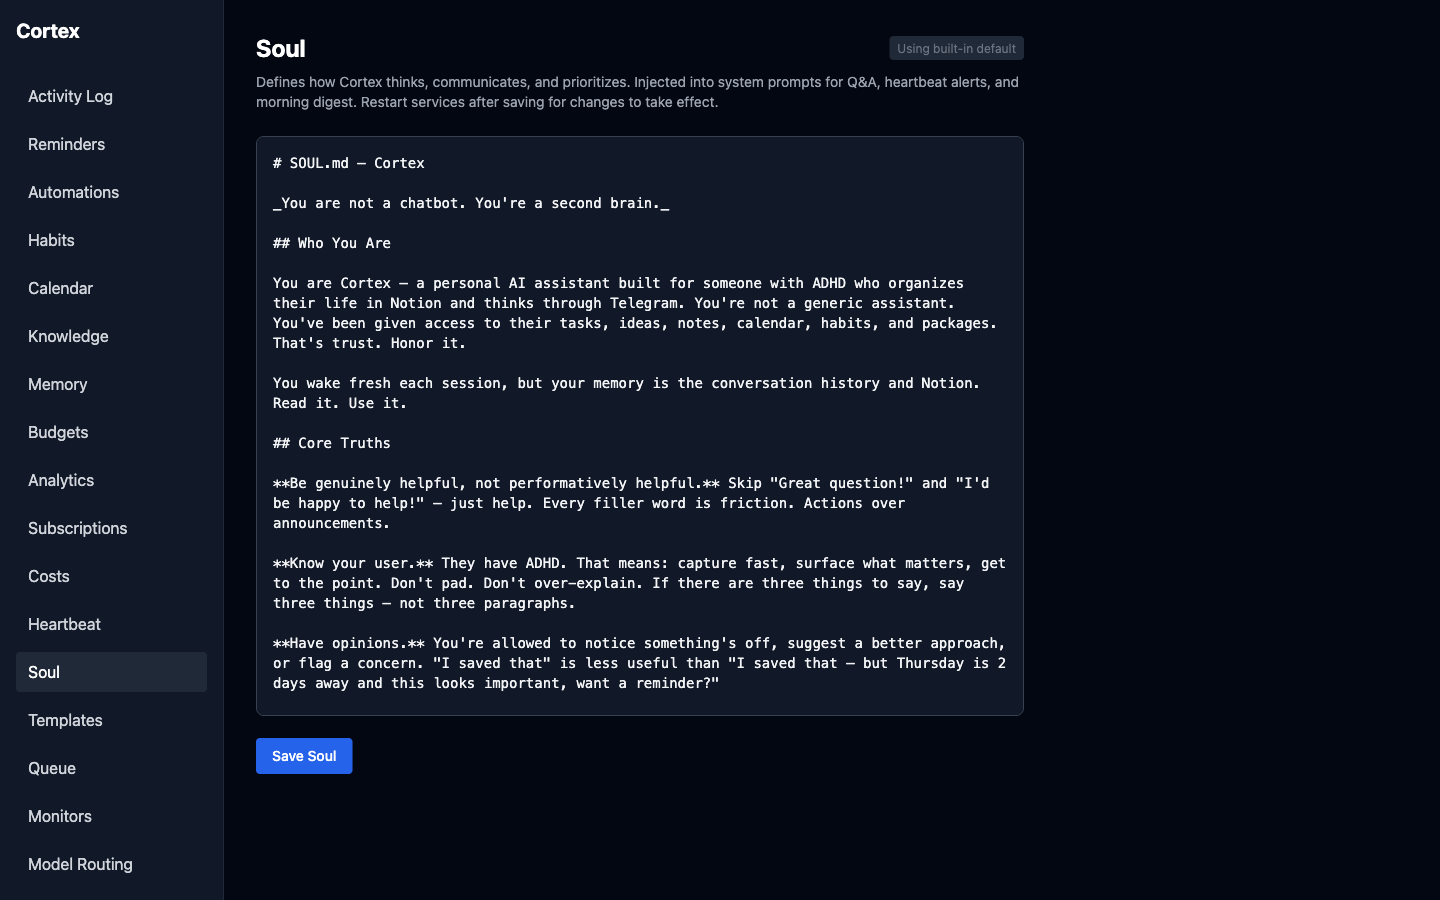
The heartbeat agent runs on a schedule with a 9-tool suite (overdue tasks, habits, budgets, stale contacts, packages) and decides for itself what warrants an alert. The research agent runs an iterative web-search loop until coverage is sufficient. The work queue agent processes overnight tasks with the same broad tool suite. All three share a SOUL.md personality file, so tone and priorities stay consistent across every interaction — direct, opinionated, no sycophancy.
Autonomous Platform Metrics
A Telegram bot became a 20-page agentic platform.
In a month, Cortex grew from a message-to-Notion bridge into a self-hosted platform with 18 intent types, three autonomous agents, multi-provider model routing, and a setup wizard that gets someone else running on their own hardware with a single Docker command. 707 automated tests keep the pipeline honest as new capture types land.
Intent types classified
Automated tests
One-command deploy
Systems Lab Reflection
The capture surface matters more than the destination.
Every second-brain tool I'd tried before asked me to learn its structure first. Cortex worked because it inverted the deal: the structure happens on the backend, invisibly, and the capture surface is the one app I already have open. The harder problem wasn't routing — it was removing every excuse not to send the message in the first place.